Meta title: Data Lineage Tracking: Complete Guide to Tools and Best Practices
Meta description: Learn how data lineage tracking works, which tools capture it, and how to roll it out. Covers column-level lineage, OpenLineage, compliance, and AI governance.
A dashboard shows the wrong revenue number. Your team scrambles. Nobody knows which table, job, or column caused the error. Sound familiar?
Lineage solves that problem. You see where data starts, how it changes, and where it lands. The guide covers definitions, methods, tools, and a step-by-step rollout plan.
What Is Data Lineage Tracking?
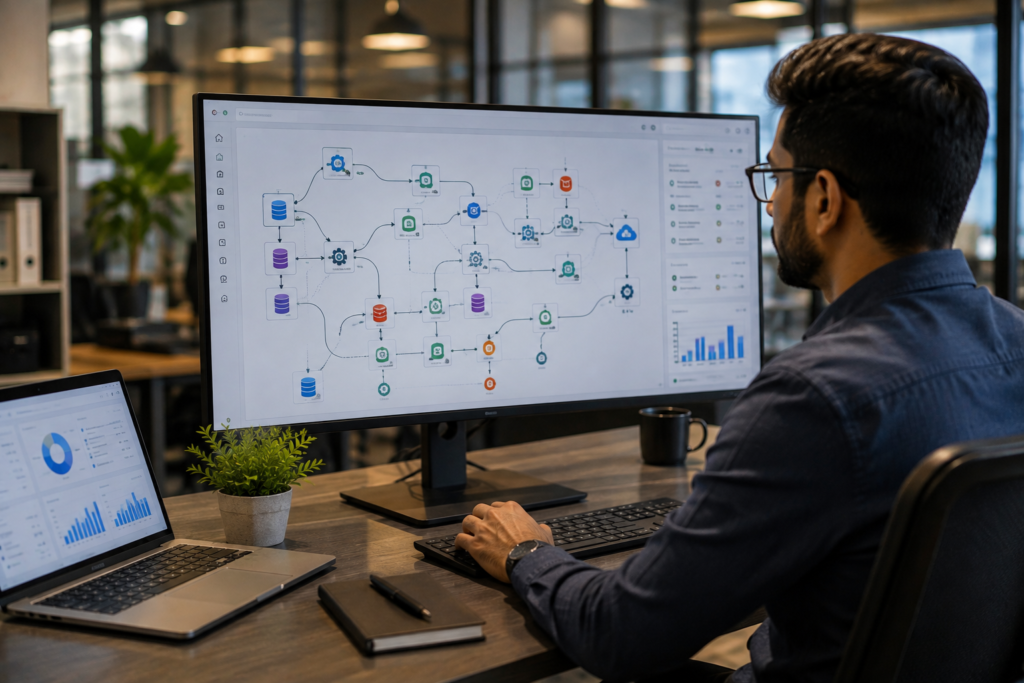
Lineage is the automated record of how data moves and changes across your systems. It follows data from its source to its final destination. Picture a GPS for your data estate.
A good lineage record captures schema updates, transformation logic, job runs, and downstream dependencies. It answers five questions: who, what, when, where, and why. Each answer builds trust in your data.
Why does trust matter so much? Gartner research shows that poor data quality costs businesses an average of $12.9 million per year. Small errors add up fast, too. A sample calculation shows that a two-point drop in lead conversion, from 10% to 8% on 500 monthly leads worth $1,000 each, loses $120,000 a year. Lineage helps you find those errors before they spread. revefirevefi
How Does Data Lineage Differ From Related Concepts?
Teams often mix up five terms. Clear definitions help you pick the right tool.
- Data lineage shows the path and transformations of data across systems.
- Data provenance records the origin and history of a single record, often as legal or scientific proof.
- Data mapping links fields between a source and a target, usually at design time.
- Data catalog stores searchable metadata. Lineage is one feature inside it.
- Data observability watches freshness, volume, and schema health. Lineage gives each alert its context.
Which one do you need? Most enterprises need all five. Lineage connects the rest.
Why Does Data Lineage Matter to Your Business?
Five benefits drive most adoption decisions.
Impact analysis. You trace forward from a planned change. You see which dashboards, models, and reports will break. Silent failures stop.
Root cause analysis. You trace backward from an error. You find the exact upstream job or column at fault. Fixes take minutes instead of days.
Regulatory compliance. Auditors want proof. Lineage gives you a verifiable trail for GDPR, CCPA, HIPAA, SOX, and BCBS 239. The stakes are high. GDPR violations can bring penalties of up to €20 million or 4% of global annual revenue, whichever is higher. revefi
AI and ML governance. Models need traceable datasets, features, and versions. Lineage supports explainability, reproducibility, and EU AI Act readiness.
Data trust and self-service. Business users trust a report when they see its origin. Trust remains a real gap. An older Gartner finding cited by Collibra predicted that more than 60% of self-service BI initiatives would fail to deliver trustworthy data. collibra
Cost matters as well. Dun & Bradstreet estimates that a record costs about $1 to handle but about $100 to correct later. Early detection saves real money. Substack
What Are the Levels of Data Lineage Granularity?
Lineage works at several layers. Each layer answers a different question.
| Level | What It Maps | Best For |
| System-level | Flows between applications, such as Salesforce to a cloud warehouse | Architecture reviews, executive views |
| Table/object-level | Databases, schemas, tables, files, and topics | Impact analysis, migrations |
| Column-level | How fields transform, aggregate, and spread | PII tracing, root cause, metric audits |
| Operational | Run times, job status, row counts, and quality test results | Pipeline health, SLA checks |
| Business lineage | Links from technical assets to glossary terms and KPIs | Governance, stewardship |
Column-level lineage delivers the most value. Do you need to prove where a customer email address travels? Only column-level detail answers that question.
How Is Data Lineage Captured Automatically?
Modern stacks avoid manual documentation. Spreadsheets go stale within weeks. Automated capture keeps maps current. Six methods dominate.
1. Parser-based extraction. Tools read SQL, Python, Spark, and dbt code. They build dependency graphs from the logic. The method suits batch pipelines.
2. Runtime event capture. Orchestrators emit metadata as jobs execute. OpenLineage is the open standard. Apache Airflow, Apache Spark, dbt, and Flink can all emit OpenLineage events. Marquez serves as a reference backend.
3. Log-based capture. Tools read query logs, change data capture (CDC) events, and Apache Kafka topics. Debezium is a common CDC source. You rebuild lineage in event-driven systems this way.
4. Native platform lineage. Cloud platforms expose lineage through built-in features. Databricks Unity Catalog, Snowflake Access History, Google Cloud Dataplex, and Microsoft Purview all offer it.
5. Pattern-based inference. Tools compare metadata patterns across systems. Accuracy varies. Use the method only when code is unavailable.
6. Manual curation. Humans add lineage for legacy systems or offline steps. Keep the volume small and reviewed.
Which method should you pick? Most teams combine two or three. Parser output plus runtime events covers the widest ground.
What Is the Difference Between Forward and Backward Lineage?
Forward lineage moves downstream. It answers, “What breaks if I change this column?” Backward lineage moves upstream. It answers, “Where did this number come from?”
Both directions matter. Engineers use forward lineage before each release. Analysts use backward lineage when a metric looks wrong. Your tool should offer both in one click.
How Does Lineage Support Compliance and AI Governance?
Regulators ask hard questions. Where does personal data live? Who accessed it? Which reports use it? Lineage answers each one.
Consider a GDPR deletion request. You must find every copy of a person’s data. A column-level map shows each table, view, and export that holds it. You would otherwise guess, and guesses create risk.
AI governance follows the same logic. A model built on flawed data makes flawed predictions. Lineage links each model version to its datasets, features, and code commits. Auditors then verify what shaped each decision. Would your team pass that audit today?
Which Data Lineage Tools Should You Consider?
The market splits into five groups. Match the group to your needs.
- Enterprise data catalogs: Collibra, Alation, Atlan, Informatica, and Microsoft Purview. They pair lineage with glossaries, policies, and workflows.
- Open-source options: OpenLineage, Marquez, DataHub, Apache Atlas, Amundsen, and OpenMetadata. They give you flexibility and community support.
- Cloud-native features: Databricks Unity Catalog, Snowflake, BigQuery with Dataplex, and AWS Glue with DataZone. They need little setup inside their own platforms.
- Specialized lineage engines: Manta, SQLFlow, and similar parsers. They excel at deep SQL and legacy code analysis.
- Observability platforms: Monte Carlo, Acceldata, and Bigeye. They connect lineage to incident response.
Ask five questions before you buy. Does the tool offer column-level lineage? Does it cover your warehouse, orchestrator, and BI tool? Can it ingest OpenLineage events? Does it expose an API? How fast does the map refresh?
How Does Data Lineage Work in Databricks, Snowflake, BigQuery, and dbt?
Each platform handles lineage in its own way.
Databricks. Unity Catalog captures lineage automatically for queries in SQL, Python, R, and Scala. It shows table and column relationships. It also links notebooks, jobs, and dashboards.
Snowflake. Access History records which objects each query reads and writes. Object dependencies show view relationships. Many catalogs pull that metadata into richer maps.
BigQuery. The Data Lineage API in Dataplex follows flows between BigQuery tables and supported services. You can also submit custom lineage events.
dbt. The ref() and source() functions build a directed acyclic graph (DAG) of your models. The dbt docs site displays the graph. Column-level lineage often needs an added tool or a dbt Cloud feature.
Python pipelines. Add the OpenLineage client or an orchestrator integration. Emit run events with inputs and outputs. A backend such as Marquez or DataHub stores the graph.
How Do You Roll Out Data Lineage Step by Step?
A phased rollout works best. Big-bang projects stall.
Step 1: Define your goal. Choose one driver first. Compliance, root cause analysis, migration, and AI governance need different depth.
Step 2: Inventory your stack. List warehouses, lakes, ETL tools, orchestrators, BI tools, and event streams. Note which ones expose metadata.
Step 3: Rank critical data paths. Start with financial reports, revenue metrics, and regulated data. Leave low-value pipelines for later.
Step 4: Choose your capture method. Match each system to parser output, runtime events, logs, or native features.
Step 5: Pick a lineage platform. Weigh coverage, column-level depth, cost, and openness.
Step 6: Connect ownership. Link each lineage node to a data steward and a glossary term. Ownership turns a map into action.
Step 7: Add quality signals. Show test results and freshness on the graph. Engineers then see each problem in context.
Step 8: Train your users. Show analysts, engineers, and compliance staff how to read the map. Adoption decides success.
Step 9: Expand in waves. Cover more pipelines each quarter. Review accuracy often.
What Challenges Will You Face?
Every rollout hits obstacles. Plan for them early. Data volume makes each one harder. Forbes reported in 2018 that about 90% of the world’s data came from the previous two years. Your estate grows faster than your documentation. collibra
- Blind spots. Legacy scripts, spreadsheets, and stored procedures hide logic. Parsers may miss dynamic SQL.
- Tool sprawl. Multiple platforms produce fragmented maps. A common standard like OpenLineage reduces the mess.
- Scale. Large estates produce graphs with millions of nodes. Filters and search become essential.
- Stale metadata. Maps decay when humans update them by hand. Automate refresh.
- Low adoption. Teams ignore tools that add work. Embed lineage in daily workflows, such as pull requests and alerts.
What Best Practices Keep Lineage Accurate?
- Start with critical paths. Prove value fast, then expand.
- Automate all capture you can. Parse code and harvest runtime metadata.
- Adopt open standards. OpenLineage keeps you portable.
- Capture column-level detail for sensitive and financial fields.
- Tie lineage to owners and business glossary terms.
- Add lineage checks to CI/CD. Block changes that break downstream assets.
- Tag sensitive data such as PII and PHI, then trace it end to end.
- Audit your maps. Compare lineage against sample pipelines each quarter.
- Document transformations in plain language, not only in code.
How Do You Measure Lineage Success?
Numbers prove value to leadership. Track six metrics:
- Share of critical pipelines with automated lineage
- Column-level coverage for regulated data
- Mean time to resolve data incidents
- Number of breaking changes caught before release
- Audit preparation time
- Active users of the lineage tool
Set a baseline first. Compare each quarter. Do incidents close faster? Then your program works.
What Are the Future Trends in Data Lineage?
Six trends shape the next few years.
Active metadata. Lineage will trigger actions, such as a paused pipeline or an alert to owners.
AI-assisted lineage. ML models will infer links in messy code and suggest fixes.
LLM and RAG lineage. Teams will trace prompts, embeddings, and source documents behind AI answers.
Data contracts. Producers will promise schemas. Lineage will show who depends on each promise.
Data mesh alignment. Domain teams will publish lineage as part of their data products.
Unified open standards. OpenLineage adoption will spread across tools.
Frequently Asked Questions
What Is Data Lineage in Simple Terms?
It is an automated record of where data comes from, how it changes, and where it goes.
What Is the Difference Between Data Lineage and Data Provenance?
Lineage maps flow across systems. Provenance documents the origin and history of specific records.
What Is Column-Level Lineage?
It traces individual fields through joins, calculations, and aggregations into reports.
Is Data Lineage Required for GDPR Compliance?
GDPR does not name lineage. However, it demands that you know where personal data lives and how it moves. Lineage makes that practical.
What Is OpenLineage?
It is an open specification that collects lineage metadata from jobs at runtime. Many orchestration and compute tools support it.
Which Tool Is Best for Data Lineage?
No single tool wins in every case. Choose based on your stack, required depth, and budget.
Can You Capture Data Lineage in Python?
Yes. Add the OpenLineage client or an orchestrator integration to emit events from your jobs.
How Does Lineage Help AI Governance?
It links models to their datasets, features, and versions. The link supports audits and explainability.
Is Data Lineage Tracking Worth Your Time?
Yes. Data grows more complex each year. Pipelines multiply. Regulations tighten. AI raises the stakes. You cannot manage data you cannot see.
Conclusion
Data lineage tracking provides a clear view of where data comes from, how it moves through systems, and how it is transformed before reaching its final destination. By documenting data sources, processes, dependencies, and destinations, organizations can improve data quality, simplify troubleshooting, strengthen governance, and support regulatory requirements. As businesses rely increasingly on complex data environments, effective data lineage tracking helps teams maintain trustworthy, transparent, and manageable data across the entire organization.
USA Parameter is a digital solutions platform focused on SEO, guest posting, content writing, online visibility, and digital growth, helping businesses strengthen their online presence and reach their target audiences.