Focus keyword: OLS
Meta title: OLS Explained: Ordinary Least Squares Formula and Code
Meta description: OLS stands for Ordinary Least Squares. Learn the OLS formula, estimators, assumptions, diagnostics, and Python and R code in one complete guide.
Secondary keywords: OLS regression, OLS estimators, OLS formula, OLS model, OLS econometrics, OLS diagnostics, OLS assumptions, OLS in machine learning, BLUE, Gauss-Markov theorem, normal equation, residuals, R-squared
OLS stands for Ordinary Least Squares. It is the most common method to estimate a linear regression model. Economists, data scientists, and researchers use it daily. A search for “old” returns several different answers, so which one do you need? You get every common definition below. Then the guide explains the statistical method in full.
What is OLS in one sentence?
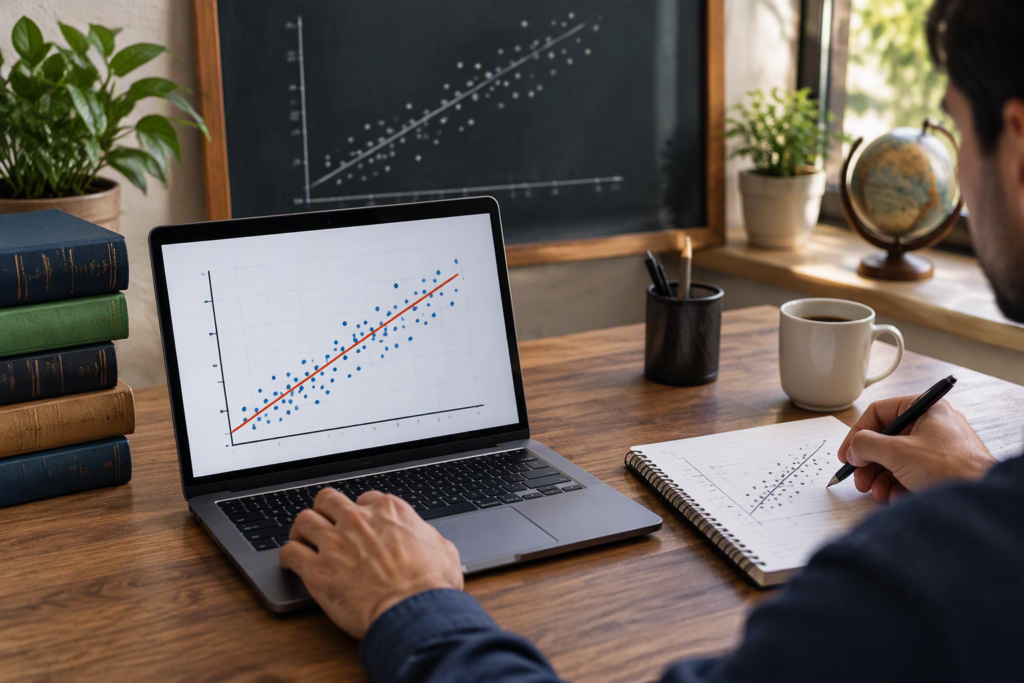
OLS finds the straight line that minimizes the sum of squared residuals. The line shows how one variable changes with another. Statisticians call the result the line of best fit.
What does OLS mean?
OLS estimates the unknown parameters of a linear regression model. The method picks the parameter values that give the smallest sum of squared residuals. A residual is the gap between an observed value and a predicted value.
Adrien-Marie Legendre published the method in 1805. Carl Friedrich Gauss released his own account in 1809 and claimed use since 1795 (Source: Wikipedia, “Ordinary least squares”). Francis Galton introduced the term “regression” in 1886 in a study of inherited height (Source: Galton, 1886).
Why did a 200-year-old method survive? Its results are simple, exact, and easy to explain.
What are the other meanings of OLS?
The acronym appears in several fields. The table separates them.
| Meaning | Field | Description |
| Ordinary Least Squares | Statistics, econometrics, machine learning | Estimates linear regression parameters |
| Open Life Science | Research community | Non-profit mentor program for open research practices |
| Online Linguistic Support | Education | EU language tool for Erasmus+ participants |
| Orientation of the Last Slot | Speedcubing | Rubik’s Cube method that solves the last F2L slot and orients the last layer together |
Related searches such as OLS estimators, OLS formula, OLS econometrics, OLS regression, OLS model, and OLS diagnostics all point to the statistical method. The rest of the guide covers that meaning.
What is OLS used for?
OLS answers one core question. How does a change in one variable relate to a change in another? You apply the method in many fields.
- Economics: You estimate how wages change with each extra year of school. The Mincer wage equation is a classic case.
- Finance: You estimate a stock’s beta. Beta is the slope of an OLS regression of stock returns on market returns.
- Sales analytics: You measure how ad spend relates to sales.
- Health research: You link lifestyle factors to clinical outcomes.
- Real estate: You predict property prices from size, location, and age.
- Science and technology: You calibrate instruments and fit trends in lab data.
Researchers value OLS for three reasons. It is simple, fast, and easy to interpret. Econometrics textbooks such as Wooldridge’s Introductory Econometrics start with OLS. R offers lm() for the method, and Python offers statsmodels and scikit-learn (Sources: Wooldridge; R documentation; statsmodels documentation).
How does the OLS formula work?
The simple linear regression model has one predictor:
y = β₀ + β₁x + ε
The symbol β₀ marks the intercept. The symbol β₁ marks the slope. The symbol ε marks the error term.
OLS minimizes the sum of squared errors (SSE):
SSE = Σ (yᵢ − ŷᵢ)²
Calculus gives a closed-form solution for the slope and the intercept:
β̂₁ = Σ (xᵢ − x̄)(yᵢ − ȳ) / Σ (xᵢ − x̄)²
β̂₀ = ȳ − β̂₁ · x̄
Multiple regression uses matrix algebra. The OLS estimator in matrix form is:
β̂ = (XᵀX)⁻¹ Xᵀy
Statisticians call it the normal equation. Have you seen it in a textbook before? It powers every OLS software package.
The matrix form delivers three more useful results:
Fitted values: ŷ = Hy, where H = X(XᵀX)⁻¹Xᵀ
Orthogonality: Xᵀe = 0
Variance: Var(β̂) = σ²(XᵀX)⁻¹
Geometry explains the first two lines. OLS projects the vector y onto the space that the columns of X span. The residual vector sits at a right angle to that space. The third line gives the variance of the estimates, and every standard error comes from it (Source: Greene, Econometric Analysis).
What does an OLS example look like in practice?
Take five data points: x = 1, 2, 3, 4, 5 and y = 2, 4, 5, 4, 5.
- The mean of x is 3. The mean of y is 4.
- The sum of cross-deviations is 6. The sum of squared x-deviations is 10.
- The slope equals 6 ÷ 10 = 0.6.
- The intercept equals 4 − 0.6 × 3 = 2.2.
The fitted line is ŷ = 2.2 + 0.6x. The table shows each residual.
| x | y | Fitted ŷ | Residual |
| 1 | 2 | 2.8 | −0.8 |
| 2 | 4 | 3.4 | 0.6 |
| 3 | 5 | 4.0 | 1.0 |
| 4 | 4 | 4.6 | −0.6 |
| 5 | 5 | 5.2 | −0.2 |
The residuals sum to zero. OLS guarantees that result when the model includes an intercept. SSE equals 2.4 and total variation equals 6, so R² equals 1 − 2.4/6 = 0.60.
You can read the result plainly. Each one-unit rise in x predicts a 0.6-unit rise in y. The line explains 60% of the variation in y. The sample holds five points, so treat it as a teaching case.
Why does OLS square the errors?
Squared errors solve three problems at once.
- Sign cancellation: Positive and negative errors would otherwise offset each other.
- Penalty weight: Large errors receive heavier penalties than small ones.
- Smooth math: The squared loss is differentiable, so calculus yields an exact solution.
Gauss linked least squares to the normal distribution of errors in 1809 (Source: Wikipedia, “Least squares”).
Large penalties create a trade-off. Outliers pull the line toward them. Check your data for extreme points before you trust the fit. Quantile regression at the median resists outliers better, because it minimizes absolute errors.
What does OLS mean in machine learning?
OLS serves as the baseline linear regression model in machine learning. It minimizes mean squared error (MSE) on the data you supply. Scikit-learn exposes it as LinearRegression and solves it with a least-squares routine from SciPy.
Small and medium datasets suit the closed-form solution. Large datasets often favor gradient descent. Matrix inversion cost grows roughly with the cube of the feature count. Feature scale changes coefficient size and leaves predictions identical.
Do you build predictive models? Start with OLS. A simple benchmark shows whether a complex model adds real value. Ridge and lasso extend OLS with penalties when predictors correlate or when you want feature selection (Source: Hastie, Tibshirani, and Friedman, The Elements of Statistical Learning).
What are OLS estimators?
OLS estimators are the coefficient values β̂ that the method computes from your sample. Each estimator is a random variable, because a new sample produces new values.
The Gauss-Markov theorem explains why statisticians trust them. The classical assumptions make OLS estimators the Best Linear Unbiased Estimators (BLUE). “Unbiased” means the average estimate equals the true parameter. “Best” means the lowest variance among all linear unbiased estimators (Source: Wikipedia, “Gauss–Markov theorem”).
Normal errors add two more benefits. Exact t-tests and F-tests hold in small samples. OLS and maximum likelihood estimation (MLE) also return identical coefficients. The two methods differ in one detail: MLE estimates the error variance with a divisor of n, while the standard OLS estimate divides by n − k.
What are the OLS assumptions?
Six assumptions support reliable OLS results.
- Linearity: The model is linear in its parameters.
- Random sample: Observations are independent draws from the population.
- Independent predictors: Each predictor adds information that the others lack. Perfect multicollinearity breaks the normal equation.
- Zero conditional mean: The error term has an expected value of zero given the predictors. Econometricians call this exogeneity.
- Homoscedasticity: The error variance stays constant across all observations.
- Uncorrelated errors: Errors stay independent of each other. Time-series data needs extra attention here.
Normal errors form a seventh, optional assumption. It matters mainly for small-sample inference.
Which assumption fails most often in your field? Exogeneity usually takes that spot in applied economics. A relevant predictor that you omit and that correlates with an included predictor shifts the coefficient. Econometricians call the result omitted variable bias.
How do you run OLS diagnostics?
Diagnostics confirm that your model meets the assumptions. Which check do you run first? Start with a plot of residuals against fitted values.
| Problem | Visual check | Statistical test | Common fix |
| Curved relationship | Residuals vs. fitted plot | Ramsey RESET | Add polynomial terms or transform variables |
| Heteroscedasticity | Residual spread plot | Breusch-Pagan, White | Robust (HC) standard errors, WLS, log transform |
| Autocorrelation | ACF plot | Durbin-Watson, Breusch-Godfrey | Newey-West errors, lagged terms |
| Multicollinearity | Correlation matrix | Variance Inflation Factor (VIF) | Drop or combine predictors, use ridge |
| Skewed or heavy-tailed errors | Q-Q plot | Shapiro-Wilk, Jarque-Bera | Transform the response, collect more data |
| Outliers and leverage | Influence plot | Cook’s distance | Investigate points, use robust regression |
| Endogeneity | Theory review | Hausman test | Instrumental variables |
A Durbin-Watson value near 2 indicates uncorrelated errors. Values near 0 signal positive autocorrelation. Values near 4 signal negative autocorrelation. A VIF above 5 or 10 signals concern, depending on the textbook you follow. Cook’s distance above 4/n flags an influential point under a common rule of thumb (Sources: Durbin and Watson; Kutner et al., Applied Linear Statistical Models).
White (1980) introduced heteroscedasticity-consistent standard errors. Newey and West (1987) extended the idea to autocorrelated errors. Both fixes keep your coefficients and repair your standard errors.
How do you read OLS regression output?
Every software package prints a similar summary. Focus on the items below.
- Coefficient: The expected change in y for a one-unit change in x, with other predictors held constant.
- Standard error: The precision of the coefficient estimate.
- t-statistic and p-value: The evidence that a coefficient differs from zero. Ronald Fisher popularized the 0.05 threshold in 1925.
- Confidence interval: The range of plausible values for the true coefficient.
- R-squared: The share of variance in y that the model explains.
- Adjusted R-squared: R-squared adjusted for the number of predictors. Use it to compare models.
- F-statistic: A joint test of all slope coefficients.
- AIC and BIC: Model comparison scores. Lower values indicate a better balance of fit and complexity.
A high R-squared alone proves little. Residual checks and sound theory carry equal weight. Which matters more to your project, prediction or explanation?
How do you run OLS in Python and R?
Python with statsmodels
python
import numpy as np
import statsmodels.api as sm
x = np.array([1, 2, 3, 4, 5])
y = np.array([2, 4, 5, 4, 5])
X = sm.add_constant(x)
model = sm.OLS(y, X).fit()
print(model.summary())
Python with scikit-learn
python
from sklearn.linear_model import LinearRegression
reg = LinearRegression().fit(x.reshape(-1, 1), y)
print(reg.intercept_, reg.coef_)
R
r
model <- lm(y ~ x)
summary(model)
All three snippets return an intercept of 2.2 and a slope of 0.6. The statsmodels and R outputs add standard errors, p-values, and diagnostics. Scikit-learn returns coefficients only.
Python diagnostics and robust errors
python
from statsmodels.stats.diagnostic import het_breuschpagan
from statsmodels.stats.stattools import durbin_watson, jarque_bera
from statsmodels.stats.outliers_influence import variance_inflation_factor
bp_stat, bp_pvalue, _, _ = het_breuschpagan(model.resid, X)
dw = durbin_watson(model.resid)
jb, jb_pvalue, skew, kurt = jarque_bera(model.resid)
robust = sm.OLS(y, X).fit(cov_type=”HC3″)
print(robust.summary())
vifs = [variance_inflation_factor(X, i) for i in range(1, X.shape[1])]
VIF needs two or more predictors.
R diagnostics and robust errors
r
library(lmtest)
library(sandwich)
library(car)
plot(model)
bptest(model)
detest(model)
vif(model)
coeftest(model, vcov = vcovHC(model, type = “HC3”))
How do you run OLS in Excel and Stata?
Excel and Stata both run OLS in a few steps.
- Excel: Open the Data Analysis ToolPak and choose Regression. The functions SLOPE, INTERCEPT, RSQ, and LINEST give quick results.
- Stata: Type regress y x. Add , vce(robust) for robust standard errors. Run estat hettest and estat vif for diagnostics.
Which tool fits your workflow? Choose the one your team already uses, because OLS output matches across all of them.
How does OLS compare with other regression methods?
| Method | Use it when | Key difference from OLS |
| Ridge regression | Predictors correlate strongly | Adds an L2 penalty that shrinks coefficients |
| Lasso regression | You want feature selection | Adds an L1 penalty that sets some coefficients to zero |
| Weighted Least Squares (WLS) | Error variance differs across observations | Gives each observation a weight |
| Generalized Least Squares (GLS) | Errors correlate or vary | Models the full error covariance |
| Logistic regression | The outcome is binary | Models probabilities with a logit link |
| Poisson regression | The outcome is a count | Models counts with a log link |
| Quantile regression | You care about medians or tails | Minimizes absolute errors at chosen quantiles |
| Robust regression | Outliers distort the fit | Reduces the weight of extreme points |
| Two-Stage Least Squares (2SLS) | A predictor correlates with the error term | Uses instrumental variables to repair endogeneity |
Hoerl and Kennard introduced ridge regression in 1970. Tibshirani introduced the lasso in 1996. Koenker and Bassett introduced quantile regression in 1978.
What are the strengths and limits of OLS?
Strengths
- Coefficients carry a clear meaning.
- Computation is fast and exact.
- Theory is mature, so confidence intervals and hypothesis tests come built in.
- Nearly every statistics package supports it.
Limits
- Outliers exert strong influence.
- OLS captures linear relationships. You can capture curves when you transform variables.
- Correlated predictors inflate coefficient variance.
- Omitted variables bias the estimates.
- Causal claims require a sound research design, regardless of fit quality.
What mistakes should you avoid with OLS?
- Extrapolation: Predictions outside your data range carry high risk.
- Correlation as causation: A strong slope shows association. Design and theory establish the cause.
- Overfit models: Extra predictors raise R-squared automatically. Adjusted R-squared and cross-validation give an honest picture.
- Skipped diagnostics: Inspect residuals before you report results.
- Wrong standard errors: Heteroscedastic data needs robust standard errors for valid inference.
- Misread R-squared: A high value signals a close fit and offers no proof of a correct model.
FAQ
What is OLS regression used for?
OLS regression estimates the linear relationship between a dependent variable and one or more predictors. Analysts use it for prediction, trend analysis, and hypothesis tests.
What is the OLS formula?
The matrix form is β̂ = (XᵀX)⁻¹Xᵀy. The simple form gives a slope of Σ(xᵢ − x̄)(yᵢ − ȳ) / Σ(xᵢ − x̄)² and an intercept of ȳ − β̂₁x̄.
What is the OLS algorithm?
The algorithm computes the coefficients that minimize the sum of squared residuals. The normal equation delivers the answer in one step.
Is OLS the same as linear regression?
Linear regression names the model. OLS names the most common estimation method for it. Ridge and lasso also fit linear models.
What does BLUE mean in OLS?
BLUE means Best Linear Unbiased Estimator. The Gauss-Markov theorem shows that OLS earns this title under the classical assumptions.
When should you choose another method?
Choose another method when the outcome is binary, a count, or heavy-tailed. Choose it also when errors correlate or predictors correlate with the error term.
Which software runs OLS?
R (lm), Python (statsmodels, scikit-learn), Stata, SAS, SPSS, and Excel all run OLS.
Conclusion
Ordinary Least Squares (OLS) is a widely used statistical method for estimating the coefficients of linear regression models. It finds the best-fitting relationship between dependent and independent variables by minimizing the sum of squared residuals. OLS is useful for understanding relationships, making predictions, and analyzing data, but its reliability depends on appropriate model assumptions and data quality. Issues such as multicollinearity, unequal error variance, and autocorrelation can affect OLS results.
USA Parameter positions itself as a digital solutions and technology platform that combines online visibility services with technology-focused content and business solutions.