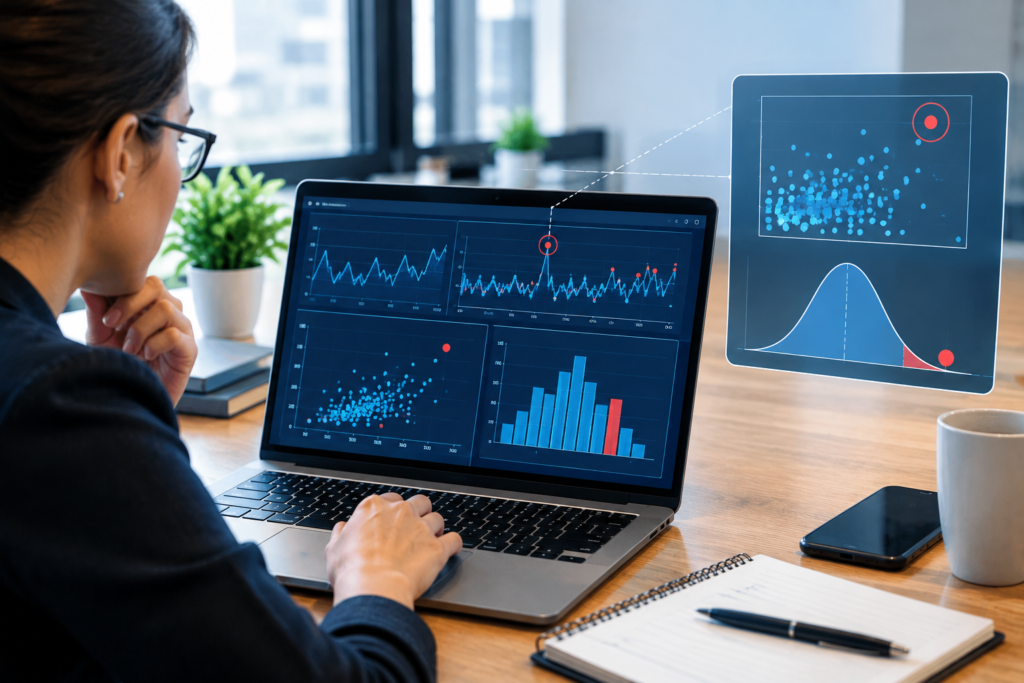
Anomaly detection algorithms find the data points that don’t belong. Fraud teams use them to catch a stolen card mid-transaction. Factory engineers use them to catch a failing bearing before it stops the line. Security teams use them to catch an intruder before data leaves the network. You need the right algorithm for your data, and this guide breaks down every major option so you can pick with confidence.
What Are Anomaly Detection Algorithms?
An anomaly detection algorithm is a statistical or machine learning tool that flags observations that deviate sharply from the norm. Analysts call these observations outliers, novelties, or exceptions depending on the field. Engineers rely on them for sensor drift. Bankers rely on them for fraud. Security analysts rely on them for intrusion attempts.
The core assumption stays consistent across every algorithm on this list: normal behavior clusters together, and anomalies sit apart from that cluster. Your job as a practitioner is to pick the algorithm whose definition of “apart” matches your data’s actual structure.
Have you already tried a generic outlier filter and watched it miss the fraud that mattered most? A mismatched algorithm is usually the cause, not bad data.
Why Does Anomaly Detection Matter Right Now?
Demand for anomaly detection keeps climbing as organizations push more processes onto sensors, transactions, and logs. Market researchers project the global anomaly detection market to grow from $6.15 billion in 2025 to $7.23 billion in 2026, a compound annual growth rate of 17.6 percent. That growth tracks a simple reality: more digital activity produces more noise, and more noise hides more fraud, failure, and threat activity inside it.
Fraud detection shows the stakes clearly. Credit card fraud drains staggering sums every year, and analysts project gross fraud losses worldwide to reach roughly $35.31 billion by 2025. Financial institutions that rely on outdated rule-based systems miss the fraud patterns that shift month to month. Machine learning models adapt, and that adaptability drives real savings. A 2023 Arab Monetary Fund study found that machine learning algorithms could improve credit card fraud detection accuracy by more than 94 percent.
You can see why choosing the right algorithm carries real financial weight. A weak model costs you missed fraud and false alarms in equal measure.
How Do Anomaly Detection Algorithms Work?
Every anomaly detection algorithm answers one question: how far does this point sit from “normal,” and by what measure? Three broad strategies answer that question in different ways.
Distance and density strategies measure how isolated a point is from its neighbors. Reconstruction strategies compress data down and then rebuild it, flagging points that rebuild poorly. Prediction strategies forecast expected values and flag points that break the forecast. Your data’s shape determines which strategy fits best, and the sections below walk through each family in detail.
What Are the Main Types of Anomaly Detection Algorithms?
How Does Isolation Forest Work?
Isolation Forest builds an ensemble of random decision trees and isolates each point by randomly splitting features. Anomalies split away from the rest of the data in far fewer steps than normal points do, because they sit in sparse regions. That isolation path length becomes the anomaly score.
Security teams favor Isolation Forest for network traffic analysis and financial teams favor it for transaction screening. The algorithm scales well across large, high-dimensional datasets, and it needs no labeled examples to start working. Do you have millions of log lines and no labeled fraud cases? Isolation Forest usually belongs on your shortlist.
How Does One-Class SVM Work?
One-Class SVM learns a tight boundary around your normal data using support vector machine math. Any new point that falls outside that boundary gets flagged as an anomaly. The method works best when your normal data forms one coherent, well-defined cluster.
Manufacturers use One-Class SVM to profile a clean baseline of “good” sensor readings when true defect examples stay scarce. The boundary approach struggles on very large or heavily overlapping datasets, so keep dataset size in mind before you commit.
How Does Local Outlier Factor (LOF) Work?
Local Outlier Factor compares a point’s local density to the density of its neighbors rather than the whole dataset. A point sitting in a sparse neighborhood relative to its neighbors earns a high anomaly score, even if the global dataset looks dense elsewhere. That local lens makes LOF strong on data with several clusters of differing density.
Retail analysts apply LOF to customer segmentation data where “normal” varies by segment. The tradeoff comes at scale: LOF’s neighbor comparisons grow computationally heavy as your dataset grows, so pair it with sampling or dimensionality reduction on large datasets.
How Do Autoencoders Detect Anomalies?
An autoencoder is a neural network trained to compress data into a smaller representation and then reconstruct the original input from that representation. Training happens exclusively on normal data, so the network learns the patterns that define “normal” behavior. A new input that reconstructs poorly produces a high reconstruction error, and that error becomes the anomaly signal.
Manufacturers use autoencoders for industrial defect spotting on image and sensor streams. Multivariate sensor data, where dozens of readings interact simultaneously, plays to the strength of deep reconstruction models. Autoencoders need more training data and compute than simpler methods, so weigh that cost against your accuracy requirements.
How Do K-Means and DBSCAN Handle Anomalies?
K-Means and DBSCAN group similar points into clusters, and points that sit far from every cluster center, or fall into sparse zones between clusters, become your outlier candidates. K-Means works fastest on roughly spherical clusters, while DBSCAN handles irregular cluster shapes and doesn’t require you to specify the number of clusters in advance.
Marketing teams use these clustering methods for ad-hoc outlier discovery inside behavioral data. A sudden spike in idle-time browsing or an unusual purchase sequence surfaces naturally once you map the clusters.
How Do LSTM and Other Recurrent Models Detect Anomalies?
Long Short-Term Memory (LSTM) networks and related recurrent architectures capture temporal dependencies inside sequential data. The model learns historical patterns and forecasts the next expected value in a sequence. A large gap between the forecast and the actual reading flags an anomaly.
Predictive maintenance teams lean on LSTM models to catch equipment failures before they happen, since sensor readings drift gradually before a hard failure. Financial markets analysts apply the same architecture to flag abnormal price or volume sequences. Sequential dependency is the key requirement here: skip LSTM if your data has no meaningful time order.
What Role Do Statistical Methods Still Play?
Z-score and interquartile range (IQR) methods remain the fastest way to catch anomalies in simple, low-dimensional numeric data. A Z-score flags any point beyond a set number of standard deviations from the mean, and an IQR method flags points beyond a multiplier of the spread between the 25th and 75th percentiles. Gaussian Mixture Models extend that idea by fitting several overlapping normal distributions to your data, then flagging points with low probability under every distribution.
Analysts reach for these methods first on smaller datasets, because they run instantly and require no training. Complex, high-dimensional, or non-linear data quickly outgrows them, though, so treat statistical methods as your baseline rather than your final answer.
How Do PCA and GANs Fit Into Anomaly Detection?
Principal Component Analysis (PCA) reduces your data to its most important dimensions and then measures how much a point deviates from that reduced representation. High reconstruction error under PCA signals an anomaly, similar to the autoencoder approach but with a simpler linear model underneath.
Generative Adversarial Networks (GANs) take a newer approach: a generator learns to produce realistic “normal” samples while a discriminator learns to separate real from generated data. Points the discriminator struggles to classify confidently often turn out to be genuine anomalies. GAN-based detection shows strong results on image and video anomaly tasks, though training stability remains a known challenge.
Anomaly Detection Algorithm Comparison Table
| Algorithm | Family | Best Use Case | Label Requirement |
| Isolation Forest | Tree-based ensemble | Fraud, network security, large datasets | Unsupervised |
| One-Class SVM | Support vector machine | Clean baseline, scarce anomalies | Semi-supervised |
| Local Outlier Factor | Density-based | Mixed-density clusters | Unsupervised |
| Autoencoders | Deep learning | Industrial defects, sensor streams | Semi-supervised |
| K-Means / DBSCAN | Clustering | Behavioral segmentation | Unsupervised |
| LSTM | Recurrent neural network | Time-series, predictive maintenance | Semi-supervised |
| Z-score / IQR | Statistical | Small, low-dimensional numeric data | Unsupervised |
| PCA | Dimensionality reduction | Linear structure, moderate dimensions | Unsupervised |
| GANs | Generative deep learning | Image and video anomalies | Semi-supervised |
Supervised vs Unsupervised vs Semi-Supervised: Which Fits Your Data?
Your labeling situation narrows the field faster than any other factor. Three categories cover almost every real-world case.
Unsupervised methods assume normal instances dominate your dataset and anomalies stay rare by definition. Isolation Forest, K-Means, DBSCAN, and LOF all fall into this category, and they work well when you have no labeled examples at all.
Semi-supervised, or one-class, methods need plenty of clean, validated “normal” records but no confirmed defect examples. One-Class SVM and autoencoders excel here, since both build a baseline profile of acceptable behavior and flag deviations from it.
Supervised methods need verified labels for both normal and anomalous states. Standard classifiers such as k-Nearest Neighbors and Decision Trees deliver higher accuracy and clearer confidence scores, provided your dataset stays reasonably balanced. Severe class imbalance, common in fraud data where anomalies make up a tiny fraction of transactions, can undercut supervised accuracy unless you apply resampling or cost-sensitive training.
How Do You Choose the Right Algorithm?
Start with three questions before you write a line of code. What kind of data are you analyzing: text, real-time sensor streams, time-series metrics, network logs, or images? Is your dataset labeled, partially labeled, or entirely unlabeled? What is the volume and dimensionality of the dataset you’re working with?
Time-dependent data points you toward LSTM or other sequence models. High-dimensional, unlabeled data points you toward Isolation Forest. Small, clean numeric datasets often need nothing more than a Z-score or IQR check. Image and video data increasingly favor autoencoders or GAN-based approaches.
Run a quick pilot before you commit to production. A small labeled validation set, even a few hundred confirmed anomalies, tells you more about real-world performance than any benchmark paper will.
Which Industries Rely on Anomaly Detection?
Cybersecurity teams use anomaly detection to catch intrusions, credential stuffing, and data exfiltration attempts before damage spreads. Finance teams use it to catch fraudulent transactions, market manipulation, and money laundering patterns. Manufacturing teams use it for predictive maintenance and defect inspection on production lines. Healthcare teams use it to flag abnormal vital signs and unusual billing patterns. Retail and marketing teams use it to catch bot traffic and unusual purchasing behavior.
Regulatory pressure compounds the demand in finance and healthcare specifically, since both sectors face strict monitoring requirements that push organizations toward automated, auditable detection systems.
How Do You Evaluate an Anomaly Detection Model?
Accuracy alone misleads you badly on anomaly detection tasks, since anomalies typically make up a tiny share of the data. A model that predicts “normal” every single time can post 99 percent accuracy while catching zero real anomalies.
Precision tells you what share of flagged anomalies were genuine. Recall tells you what share of true anomalies your model actually caught. The F1 score balances both metrics into a single number, and the AUC-ROC curve shows how your model performs across every possible decision threshold. Track all four metrics together, and watch precision and recall in tandem rather than in isolation. A model tuned purely for recall will bury your team in false alarms.
Which Tools and Libraries Support Anomaly Detection?
Python dominates this space. Scikit-learn ships Isolation Forest, One-Class SVM, and LOF out of the box. PyOD packages more than 40 detection algorithms under one consistent interface, spanning classic statistical methods through deep learning models. TensorFlow and PyTorch handle custom autoencoder and GAN architectures when off-the-shelf models fall short. Time-series specialists often reach for Facebook’s Prophet or dedicated sequence libraries built on top of PyTorch.
Cloud platforms now bundle managed anomaly detection services too, which cuts setup time for teams that lack deep ML infrastructure in-house.
What Challenges Do Anomaly Detection Algorithms Face?
Class imbalance ranks as the toughest recurring challenge. Genuine anomalies often make up less than one percent of a dataset, and that imbalance skews naive models toward predicting “normal” every time. Concept drift creates a second challenge: normal behavior shifts over months, so a model trained on last year’s data slowly loses accuracy unless you retrain on a schedule.
High dimensionality adds a third layer of difficulty. Distance and density measures lose meaning as feature counts climb, a problem researchers call the curse of dimensionality. Dimensionality reduction techniques such as PCA often become a necessary preprocessing step rather than an optional one.
Frequently Asked Questions
What is the best anomaly detection algorithm overall?
No single algorithm wins across every use case. Isolation Forest handles large, high-dimensional, unlabeled data well. LSTM models handle time-series data well. Your data’s structure decides the winner, not a general ranking.
Can anomaly detection algorithms run in real time?
Yes. Isolation Forest, statistical thresholding, and lightweight autoencoders all support real-time scoring on streaming data. Heavier deep learning models need optimization, such as model distillation or GPU inference, to hit real-time latency targets.
How much data do you need to train an anomaly detection model?
Statistical and tree-based methods can work with a few thousand records. Deep learning methods such as autoencoders and GANs typically need tens of thousands of records or more to learn a reliable baseline.
Do anomaly detection algorithms require labeled data?
Most don’t. Unsupervised methods such as Isolation Forest, K-Means, and DBSCAN run without any labels. Semi-supervised methods need labeled normal examples only. Supervised methods need labels for both normal and anomalous cases.
Conclusion
Anomaly detection algorithms play an important role in identifying unusual patterns, behaviors, and events across large datasets. By using statistical methods, machine learning, and AI techniques, organizations can detect potential fraud, security threats, system failures, and operational issues more efficiently. Selecting the right algorithm depends on factors such as data characteristics, accuracy requirements, scalability, and the type of anomalies being detected. As data volumes continue to grow, effective anomaly detection can help organizations make faster decisions and respond to potential problems proactively.
USA Parameter — Driving Digital Growth Through SEO, Content, and Innovative Digital Solutions.