Retrieval-Augmented Generation, known as RAG, connects a large language model to an external knowledge base and pulls in fresh, verified information before the model writes an answer. Meta AI researchers introduced the technique in a 2020 paper, and the idea reshaped how companies build AI systems. Instead of trusting a model’s frozen training data, RAG hands the model real documents at the moment of the query. Think of it as an open-book exam for AI: the model still reasons and writes, but it checks its notes first.
You pronounce RAG the same way you say the word “rag” — one syllable, rhymes with “bag.” People often say it as a full acronym too (“R-A-G”), but the single-syllable version dominates in conversation and in most YouTube explainer videos.
Enterprise adoption tells the real story here. Market estimates for global RAG spending in 2025 sit between $1.9 billion and $3.3 billion, depending on the research firm, and other forecasts put the market on a path toward roughly $74.5 billion by 2034. Growth like that rarely happens without a real problem behind it. So what problem does RAG actually solve? supabasecyfuture
Why Did Organizations Start Using RAG?
Early large language model deployments shared one failure pattern: confident, detailed, completely wrong answers. A model would state outdated regulations as current law or invent a product spec that never existed. Researchers traced this back to a structural gap, not a lack of intelligence. Models carry a training cutoff, a limited context window, and zero built-in access to your company’s private data.
RAG closes that gap. A Journal of Medical Internet Research study found hallucination rates of 39.6% for GPT-3.5, 28.6% for GPT-4, and 91.4% for Bard in systematic review tasks — numbers that explain why trust became the industry’s central problem. Grounding responses in retrieved, sourced documents directly attacks that failure rate. RAG can cut hallucinations by more than 40% and lift accuracy substantially, according to recent industry data. cmarixcmarix
Trust gaps show up in survey data too. Gartner research found that 53% of consumers distrust AI-powered search results, and that number climbs further in regulated industries like healthcare and finance. Would you deploy a customer-facing AI tool your own users don’t believe? Most enterprise teams decided the answer was no, and RAG became their fix. cmarix
How Does the RAG Pipeline Actually Work?
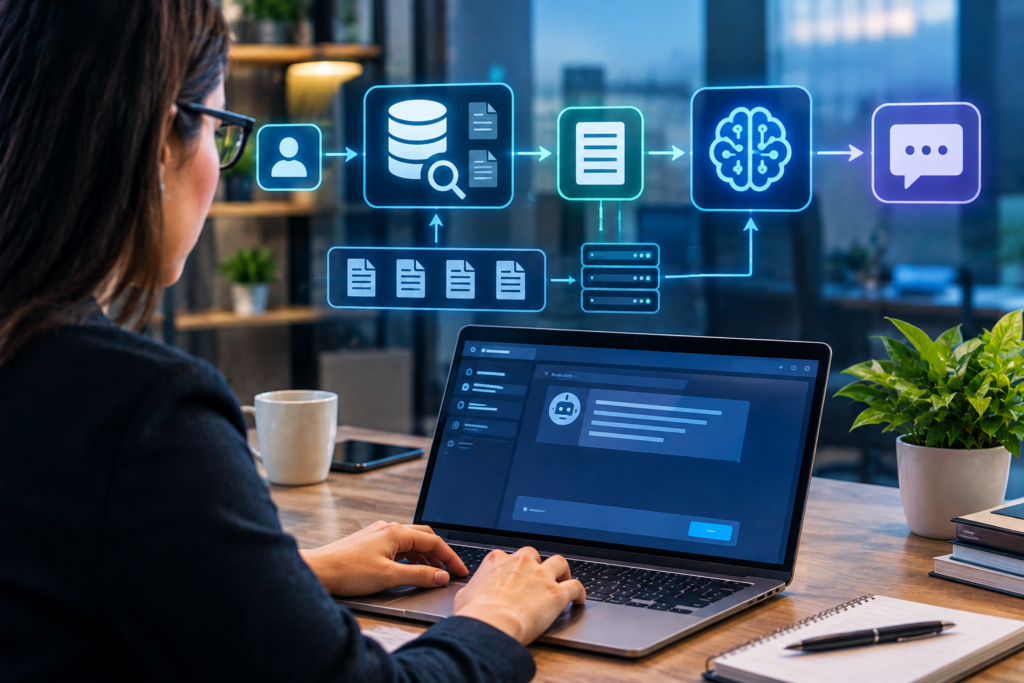
Four stages carry a query from raw text to a grounded answer. Each stage solves a specific piece of the retrieval problem.
Indexing comes first. Your documents — PDFs, wikis, spreadsheets, support tickets — get parsed and broken into smaller chunks. An embedding model converts each chunk into a numerical vector, a compact representation of its meaning, and stores that vector inside a vector database. Good chunking strategy matters enormously here; chunks that are too large drown the signal, and chunks that are too small lose context.
Retrieval happens next. Your query gets converted into a vector using that same embedding model, then the system runs a similarity search — often cosine similarity — across the vector store. The top-ranked chunks come back as candidates.
Augmentation merges the pieces. The system combines your original question with the retrieved chunks inside a structured prompt template. Nothing fancy happens here mechanically, but the quality of this template shapes everything downstream.
Generation closes the loop. The LLM receives the augmented prompt and writes a response grounded in the retrieved facts rather than in memory alone. You get an answer, and — in well-built systems — a citation trail back to the source document.
Do you see why each stage matters on its own? A weak embedding model breaks retrieval even with perfect indexing. A sloppy prompt template wastes great retrieval. Production RAG systems live or die on the weakest link in this chain.
What Is RAG vs LLM? How Do They Differ?
An LLM is the model itself — the neural network trained on massive text corpora that predicts and generates language. RAG is not a model. RAG is an architecture that sits around a model and feeds it live, external information. Put simply: the LLM writes, and RAG decides what the LLM gets to read first.
A useful comparison: a brilliant analyst locked in a room with no internet access represents a plain LLM. Give that same analyst a live research assistant who hands over exactly the right documents before each question, and you get a RAG system. The analyst’s raw skill stays constant. The quality of the answers changes completely, because the inputs changed.
Is ChatGPT a RAG Model?
ChatGPT itself is a large language model, not a RAG system by default. Browsing mode changes that picture, though. When ChatGPT searches the web or reads an uploaded file mid-conversation, it performs a live retrieval step and feeds those results back into its own context — a lightweight form of RAG in action. Standard GPT training and inference, without those tools switched on, generates answers purely from learned parameters.
Enterprise deployments built on GPT models go further. Companies connect GPT to internal vector databases through frameworks like LangChain or LlamaIndex, and that combination — GPT plus a custom retrieval layer — counts as a true production RAG system, distinct from the consumer chatbot experience.
What Is an LLM, and What Are the Main Types of LLM?
A large language model is a neural network trained on enormous volumes of text to predict the next word in a sequence, and that simple training objective produces surprisingly capable reasoning, writing, and coding behavior at scale. Several categories exist:
- Foundation models — broad, general-purpose models trained on diverse internet-scale data (GPT, Claude, Gemini, Llama).
- Fine-tuned models — foundation models further trained on narrow, domain-specific data for a specialized task.
- Instruction-tuned models — models specifically trained to follow user commands and hold conversations rather than just complete text.
- Multimodal models — models that process text alongside images, audio, or video within a single architecture.
- Open-weight models — models with publicly released parameters, such as Llama and Mistral, that developers can self-host and modify.
- Mixture-of-experts models — architectures that route each query to a subset of specialized internal “expert” networks rather than activating the full model every time.
RAG works with any of these model types. The retrieval layer stays separate from the model architecture, so you can swap the underlying LLM without rebuilding your knowledge base.
What Are the Key Benefits of RAG?
Four benefits explain why RAG became the enterprise default rather than a niche technique.
Hallucination reduction tops the list. Grounded answers, tied to verified external sources, cut the fabrication rate dramatically compared to a model answering from memory alone.
Fresh knowledge follows close behind. A vector database updates in real time. Your model’s training data stays frozen at a cutoff date, but the documents feeding RAG can update every hour if your pipeline supports it.
Cost efficiency matters just as much. Fine-tuning a foundation model on your proprietary data costs real money and real engineering time. Pointing a retrieval system at your existing document store costs far less and ships far faster.
Private data access rounds out the list. Enterprise RAG systems query internal wikis, contracts, and chat logs without ever exposing that data to a public model provider’s training pipeline. Security teams generally prefer that architecture over any alternative that risks data leakage.
Which of these four matters most for your use case? A customer support team probably cares most about freshness. A legal team probably cares most about private data access and citation trails. Your priority list should shape your architecture decisions from day one.
What Are the Different Types of RAG?
RAG architecture evolved through three broad generations, and knowing which generation fits your problem saves months of rework.
Naive RAG relies on basic vector similarity search alone — chunk, embed, retrieve, generate. Simple to build, cheap to run, and good enough for straightforward FAQ-style knowledge bases.
Advanced RAG adds reranking, query rewriting, and hybrid search that blends vector similarity with keyword matching. These additions fix the common failure where the “obviously correct” document ranks fourth instead of first.
Agentic RAG goes further still. The AI dynamically decides when to search, how to rewrite a poorly phrased query, and how to verify retrieved facts before it answers. Some agentic systems even chain multiple retrieval steps together, checking one source against another before committing to a response.
Vectorless RAG skips embeddings entirely for certain use cases, and instead queries knowledge graphs or relational SQL databases directly — a strong fit for highly structured enterprise data where exact relationships matter more than semantic similarity.
GraphRAG deserves a separate mention. Traditional vector retrieval struggles with questions that require connecting facts across many documents. GraphRAG builds a knowledge graph of entities and relationships first, then retrieval and reasoning happen across that graph — a better fit for complex, multi-hop queries than plain vector search.
Why Do People Say RAG Is Outdated?
This debate flared up as context windows expanded dramatically. Claude Sonnet 4.6 and several competing models now support roughly a million tokens of context, and that expansion raised an honest question across engineering teams: if you can paste your entire knowledge base into a single prompt, why maintain a retrieval pipeline at all? toolhalla
The data pushes back against the “RAG is dead” argument, though. Research from vector database provider Chroma found that accuracy drops between 20% and 50% once a prompt passes roughly 32,000 tokens, even on models marketed with million-token windows. A focused 20,000-token context built from the right retrieved chunks consistently beats a bloated 200,000-token context stuffed with everything you own. toolhalla
Cost reinforces the same conclusion. Sending your full document set with every single query multiplies your token bill fast, while a retrieval step that narrows the field down first keeps spending predictable. Real-time data adds another wrinkle: a stuffed context window stays frozen at whatever you loaded when the conversation started, but a live RAG pipeline can hit an API or a database and pull the latest number on demand.
The honest 2026 answer sits between the two extremes. Traditional RAG still handles static knowledge retrieval well, while newer approaches like GraphRAG suit complex, multi-source queries better, and emerging agentic memory systems are starting to take over certain roles in adaptive AI agents that need to learn and adapt over time. Most production teams in 2026 run a hybrid: a large context window for working memory, paired with RAG for reliable, current knowledge access. Would you bet your production system on a single approach when a hybrid clearly performs better? Most engineering leads already answered that question with their architecture diagrams. VentureBeatVentureBeat
How Does Microsoft Copilot Use RAG?
Microsoft Copilot grounds its answers in your organization’s Microsoft 365 data — emails, documents, chats, and calendar entries — through a retrieval layer called Microsoft Graph. A query triggers a search across content you already have permission to see, and Copilot feeds those results into the model before it generates a response. That grounding step keeps Copilot’s answers tied to your actual company data rather than generic training knowledge, and it respects existing permission boundaries so users never see content outside their access level.
What Are Real-World Examples of RAG in Action?
A few concrete scenarios show the pattern clearly:
- A customer support chatbot retrieves your company’s current return policy from an internal knowledge base before it answers a shopper’s question, rather than guessing from outdated training data.
- A legal research assistant pulls the exact clauses from a 200-page contract and cites the page number, instead of summarizing from memory.
- A developer tool searches your private codebase and pulls the three most relevant files before it suggests a fix, rather than hallucinating a function that doesn’t exist in your repo.
- A financial analyst tool retrieves this morning’s market data through a live API call before it writes a summary, keeping the analysis current down to the hour.
Each example shares the same backbone: retrieve first, generate second, cite the source.
Where Can You Go Deeper on RAG?
Foundational reading includes the original Meta AI research documented on Wikipedia, AWS’s technical breakdown, and Google Cloud’s implementation guide for production deployment patterns.
FAQs
1. What is Retrieval-Augmented Generation (RAG)?
Retrieval-Augmented Generation is an AI approach that combines information retrieval with generative AI. It retrieves relevant information from external data sources and provides that context to a language model to generate a more informed response.
2. How does Retrieval-Augmented Generation work?
RAG generally works in three steps: retrieving relevant information from a knowledge source, adding that information to the model’s context, and generating an answer based on the retrieved content.
3. What are the benefits of RAG?
RAG can improve the relevance and accuracy of AI-generated responses, provide access to updated information, reduce reliance on information stored solely within a model, and help organizations use their own private knowledge bases.
4. What is the difference between RAG and fine-tuning?
RAG gives an AI model access to external information at query time, while fine-tuning changes the model’s learned parameters through additional training. RAG is often useful when information changes frequently or comes from a specific knowledge base.
5. Can RAG reduce AI hallucinations?
RAG can help reduce hallucinations by supplying the model with relevant source information. However, it does not eliminate hallucinations completely, since the quality of retrieval and the model’s generation still affect the final response.
6. Where is RAG used?
RAG can be used for customer support, enterprise search, document analysis, research assistants, knowledge management, chatbots, and applications that need answers based on specialized or frequently updated information.
7. What data sources can be used with RAG?
RAG systems can retrieve information from documents, databases, websites, knowledge bases, PDFs, product catalogs, internal company content, and other structured or unstructured data sources.
Conclusion
Retrieval-Augmented Generation has become an important approach for building AI systems that can work with external and specialized information. By combining information retrieval with generative models, RAG can provide responses that are more relevant to a particular knowledge base and can incorporate information that may not have been available during the model’s original training. As AI applications continue to expand, RAG can play an important role in enterprise search, customer support, research, and knowledge management.
USA Parameter provides practical insights, reliable information, and useful resources to help readers make informed decisions and stay updated.